
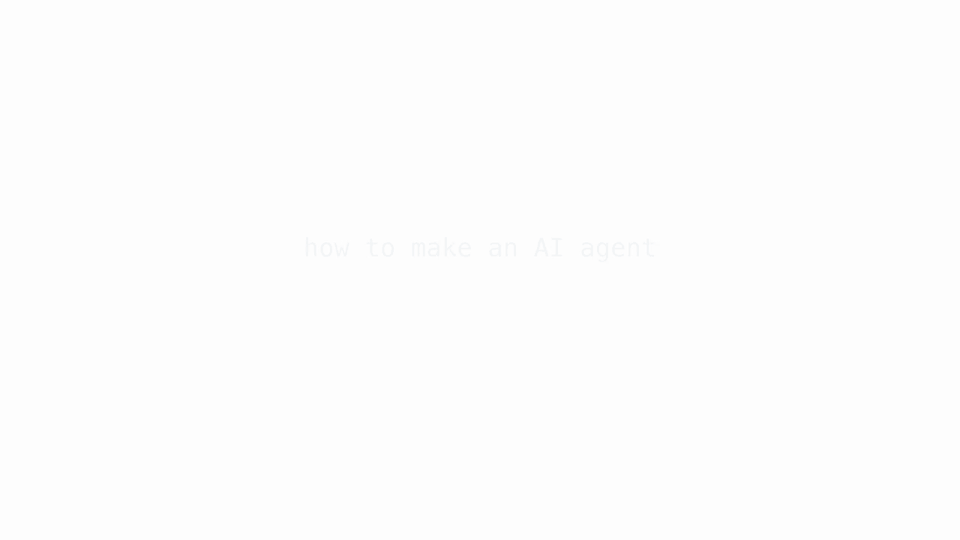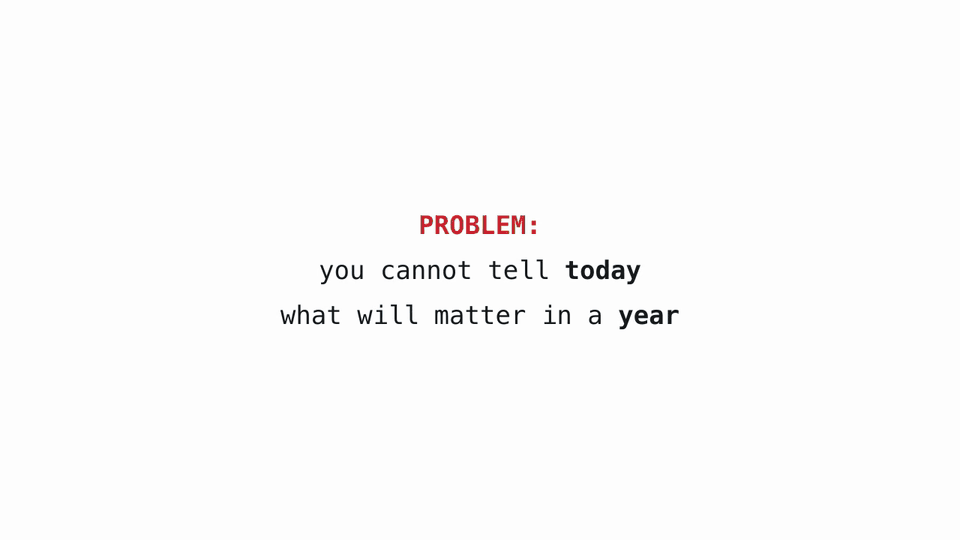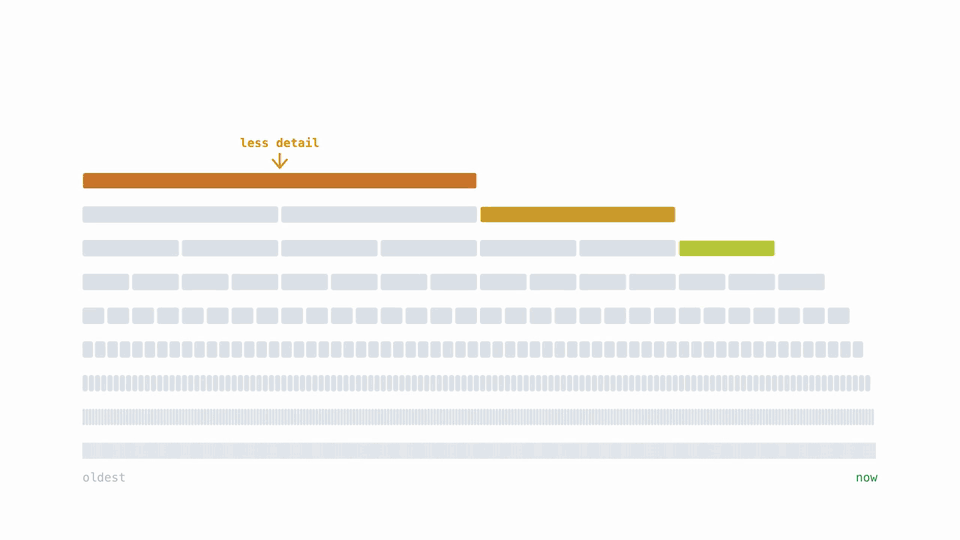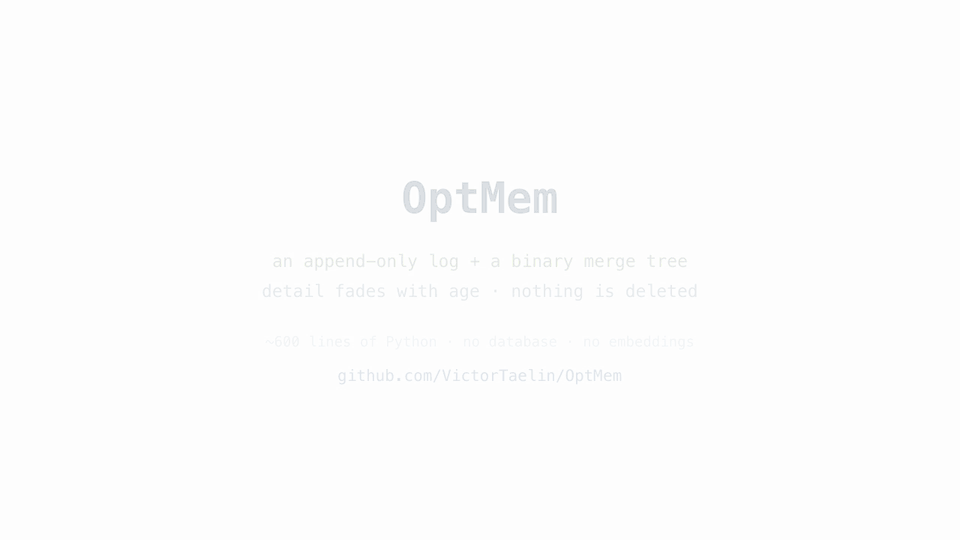
1. The Core Bottleneck: What Engineering Flaw Does It Shatter?
Large language models suffer from natural memory fragmentation across multi-turn sessions and project iterations. Existing architectures overwhelmingly rely on vector databases or heavy Retrieval-Augmented Generation systems, introducing high embedding compute costs, complex index maintenance overhead, and brittle recall tuning. VictorTaelin's OptMem discards these heavy external facilities, returning directly to the physical laws of the file system. The project leverages a 426-token base prompt to hand control back to the agent itself, utilizing a single Python script to manage the entire read-write lifecycle.
💡 Core Architectural Insight: By solidifying memories into physical files and embedding state machine instructions directly into the prompt, OptMem bypasses all network overhead and middleware friction, achieving persistent memory that surpasses commercial products using primitive local file operations.
2. Core Architecture and Data Flow Analysis
The runtime boundary of OptMem is exceptionally clean, featuring no complex microservice decomposition. The entire system consists of a single Python script and a local directory. The memo command directly manipulates the append-only log file while caching tree-like summaries in an isolated folder. Agents are forced to execute the wake command at the start of every session, subsequently triggering compression or archiving via note during routine workflows.
[ Agent / LLM ] ---> [ memo wake / note ] ---> [ ~/.optmem/memory/LOG.txt ]
                             │
                             ▼
                     [ TREE/ Summaries ]
All records utilize fixed-width formatting where physical position directly equates to identity. When processing one million records occupying 608MB of disk space, executing the wake command takes a mere 0.03 seconds. This design avoids CPU jitter caused by dynamic parsing, compressing computational complexity down to a constant level.
3. Technology Selection and Hardcore Benchmarks
| Evaluation Dimension | OptMem (This Solution) | Traditional Vector RAG | Commercial Cloud Memory | Production Benefits |
|---|---|---|---|---|
| External Dependencies | Zero dependencies (Pure Python) | Vector DB, Embedding API | Proprietary SDK, SaaS Account | Eliminates supply chain fragility, 100% offline-ready |
| Query Latency | 0.03s (1M records) | 200ms - 800ms | 100ms - 500ms | Completely eradicates network roundtrip latency |
| Storage Cost | Raw local text files | High vector index overhead | Usage-based billing | Hardware costs compressed to zero |
| Maintainability | Single file replacement & upgrade | Complex refactoring & migration | Deep lock-in to vendor ecosystem | Escapes platform lock-in and version deprecation |
This benchmark data exposes the architectural redundancy of traditional approaches in engineering deployment. OptMem proves that local text serialization and precise tree folding outperform complex embedding space retrieval in most agent workloads.
4. Hands-on Geek Practice: Building a Minimal Loop from Scratch
Execute the official installation script directly in a Unix-like environment, which automatically fetches the core script and initializes the directory structure.
# Fetch and install the OptMem core tool from the official repository
curl -fsSL https://raw.githubusercontent.com/VictorTaelin/OptMem/main/install.sh | sh
Upon completion, the script outputs a Markdown-formatted instruction block. Developers must copy and paste this output directly to the top of their agent's configuration file (e.g., AGENTS.md or CLAUDE.md). Below is the minimal validation script for agent invocation and script interaction:
import subprocess
import os

# Set environment variable to customize the memory directory
os.environ["MEMORY_DIR"] = os.path.expanduser("~/.optmem/memory")

# Simulate invoking the wake command at session startup to read memory context
def agent_wake():
    result = subprocess.run(["~/.optmem/memo", "wake"], capture_output=True, text=True, shell=True)
    return result.stdout

# Simulate recording a new memory during routine development, limited to 280 bytes per line
def agent_note(memory_text):
    cmd = f"~/.optmem/memo note \"{memory_text}\"";
    result = subprocess.run(cmd, capture_output=True, text=True, shell=True)
    return result.stdout

if __name__ == "__main__":
    print("=== Wake Output ===")
    print(agent_wake()[:500])
Executing memo wake returns recent memories according to the configured WAKE_LINES threshold, while executing memo note appends new events to the physical log.
5. Production Gotchas and Pitfalls
In production environments featuring multi-process or parallel subagent concurrent writes, simple append-only logging requires careful management to prevent write contention caused by missing file locks.
⚠️ Gotcha Warning: Concurrent Write Collisions: In multi-instance parallel execution scenarios, subagents are strictly prohibited from invoking
memocommands directly. The official documentation explicitly states that parallel sessions must be managed centrally by the master process; unauthorized subagent writes will cause log corruption and summary tree invalidation.⚠️ Gotcha Warning: Prompt Pollution and Redundancy: Developers must never store lengthy, unformatted debug logs inside
note. Every memory entry must remain under 280 bytes and contain high-density architectural decisions or factual data, otherwise the reading budget allocated byWAKE_LINESwill be exhausted instantly.