
1. The Core Bottleneck: What Engineering Flaws Does It Shatter?
Deploying local LLMs on Apple Silicon frequently exposes performance bottlenecks stemming from the serial execution inefficiencies of standard inference frameworks. Traditional solutions like mlx-lm struggle to maintain high streaming throughput during multi-turn tool-calling loops required by modern coding agents, suffering from redundant KV cache recomputation and context-switching latencies. Rapid-MLX bypasses general-purpose wrappers by directly restructuring the execution pipeline for Apple's unified memory architecture. By integrating continuous batching, speculative decoding, and dedicated tool-calling syntax parsers, Rapid-MLX pushes local token generation speeds to hardware limits.
💡 Architectural Insight: By making speculative decoding the default execution path and bundling 27 specialized tool parsers, Rapid-MLX transitions local inference servers from toy sandboxes into production-grade agent backends.
2. Core Architecture and Data Flow Analysis
Rapid-MLX decouples its parser layer, memory manager, and execution engine. Once a client sends a request via OpenAI- or Anthropic-compatible endpoints, the gateway processes tool structures through modular parsers before routing the payload into the memory layer for Radix prefix matching and state snapshot restoration.
[ Client / CLI ] ---> [ Gateway / Tool Parsers ] ---> [ Radix Memory Layer ]
                                                               │
                                                               ▼
                      [ Dynamic Execution Engine (MTP + Lookup) ]
The core competitive advantage lies in dual-track speculative decoding (multi-token prediction plus prompt lookup), which enables parallel candidate token generation during structured code editing tasks. Simultaneously, the memory layer persists historical prompt KV caches to local disk, restoring memory maps upon restart to eliminate model reloading delays.
3. Technical Selection and Hardcore Benchmarking
| Evaluation Dimension | This Solution (Rapid-MLX) | Traditional Paradigm (mlx-lm) |
Typical Competitor (Ollama) | Production Benefit |
|---|---|---|---|---|
| Inference Engine | Native Apple MLX backend | Apple MLX (mlx_lm.server) |
GGML / GGUF hybrid engine | Maximizes unified memory bandwidth |
| Concurrency Control | Continuous batching | Single task or basic queue | OLLAMA_NUM_PARALLEL limits |
Non-blocking multi-agent requests |
| KV Cache Strategy | Radix tree + disk state snapshots | In-memory temporary cache | Context reuse without snapshots | Zero cold-start latency on restart |
| Tool-Call Parsing | 27 built-in parser modules | Relies on model tokenizer declarations | Standard compatibility subset | Eliminates agent tool-parsing crashes |
Benchmark data confirms that Rapid-MLX preserves full compatibility with Safetensors weights in the MLX ecosystem while bridging Ollama's concurrency gaps on Apple hardware, outperforming standard mlx-lm in parsing robustness.
4. Hands-on Geek Guide: Building the Minimal Closed Loop
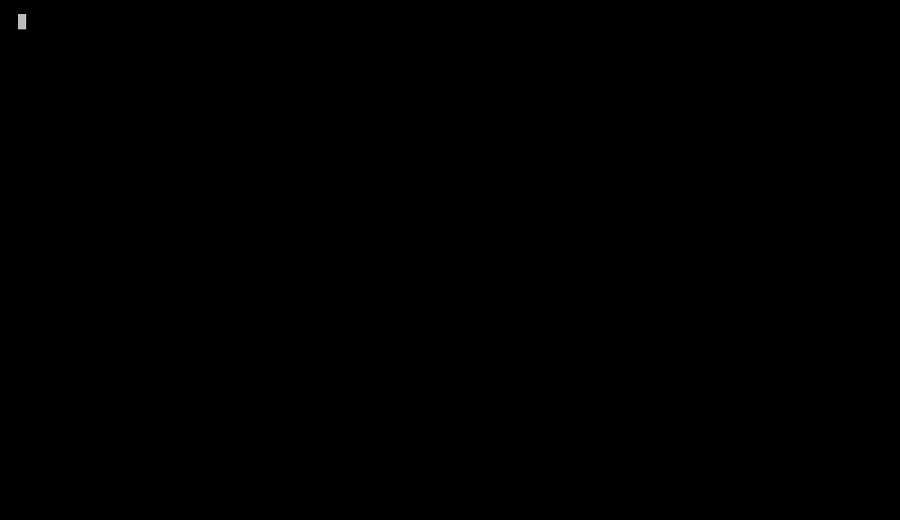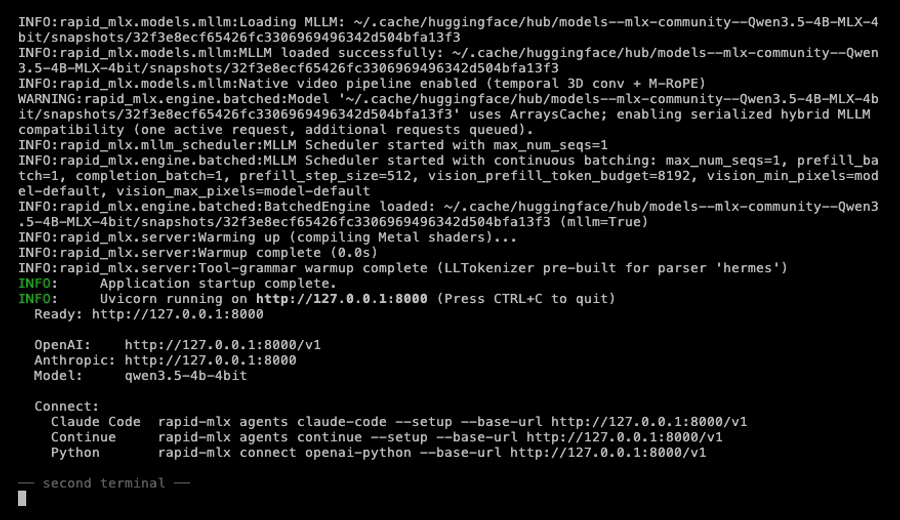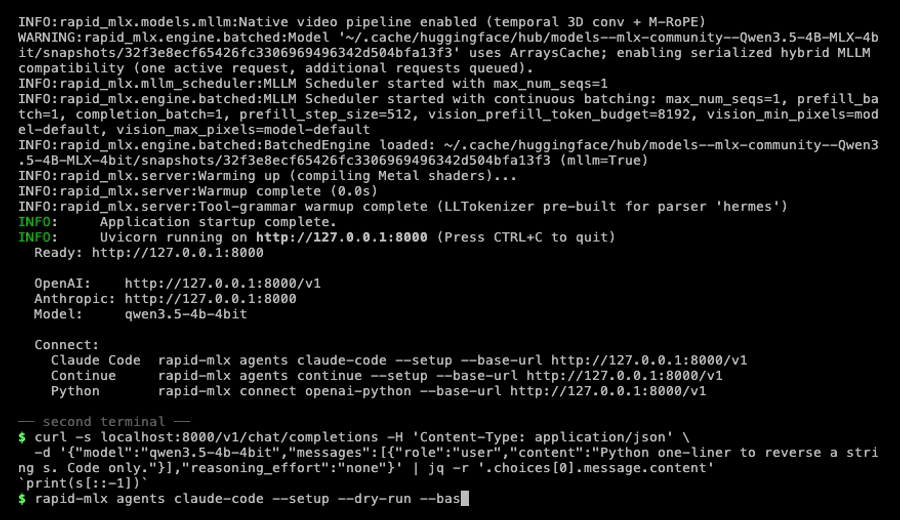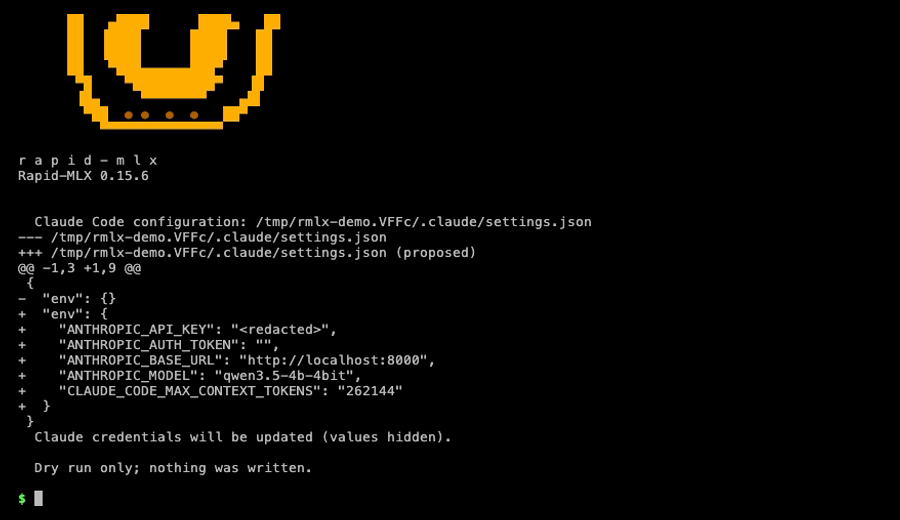
To bootstrap a local Rapid-MLX server and execute your first OpenAI-compatible API request, install the macOS desktop tool via Homebrew or deploy via Python for production workloads.
# Install macOS desktop and server components via Homebrew
brew install rapid-mlx

# Alternatively, set up a Python virtual environment and install the package
pip install rapid-mlx

# Launch the local compatible server for a specific model on port 8000
python -m rapid_mlx.server --model Qwen/Qwen3.5-9B-Instruct-4bit --port 8000
Verify the deployment with a Python script executing standard streaming tool calls and generation tasks:
import openai

# Initialize the OpenAI client pointing to the local Rapid-MLX server
client = openai.OpenAI(
    base_url="http://localhost:8000/v1",
    api_key="not-needed"
)

# Initiate a streaming chat completion request triggering speculative decoding
response = client.chat.completions.create(
    model="Qwen/Qwen3.5-9B-Instruct-4bit",
    messages=[
        {"role": "system", "content": "You are a precise coding agent."},
        {"role": "user", "content": "Write a python function to compute fibonacci numbers."}
    ],
    stream=True,
    temperature=0.0
)

# Consume streaming tokens in real time
for chunk in response:
    delta = chunk.choices[0].delta
    if delta.content:
        print(delta.content, end="", flush=True)
Running this script streams Python code at speeds approaching hardware limits, significantly reducing generation latency compared to standard setups.
5. Production Gotchas and Deployment Warnings
Deploying Rapid-MLX within complex production coding agent workflows requires adherence to specific hardware and software constraints to mitigate architectural risks.
⚠️ Gotcha Warning [Hardware Platform Restriction]: Rapid-MLX acceleration features are tightly coupled with Apple Silicon architectures. Official desktop and native binary builds for Windows and Linux are currently unavailable; do not use it as a heterogeneous inference node in cross-platform clusters.
⚠️ Gotcha Warning [Default Speculative Decoding Flags]: Smaller parameter models like Qwen3.5-4B have speculative decoding disabled by default. Forcing large multi-token prediction heads on lower-tier chips can cause memory bandwidth contention; always validate throughput via benchmarks before altering default hyperparameters.