
1. The Core Bottleneck: What Engineering Dead Ends Does It Break?
Mainstream search indexing remains bound to traditional web crawlers and authority-weighted ranking algorithms. When developers investigate a low-level technology, an open-source maintainer, or a commercial entity in real time, Google typically returns months-old stale blog posts, official PR releases, or SEO garbage pages. The actual technical discourse, sharp criticisms from frontline engineers, and debugging logs for product defects are scattered across Reddit comment sections, X posts, YouTube video transcripts, and GitHub commit histories. These platforms form isolated walled gardens with proprietary authentication schemes and strict rate limits.
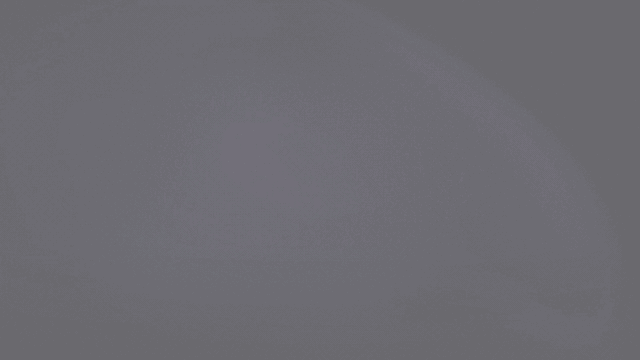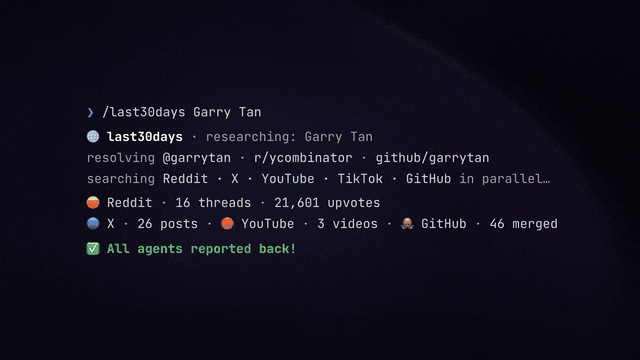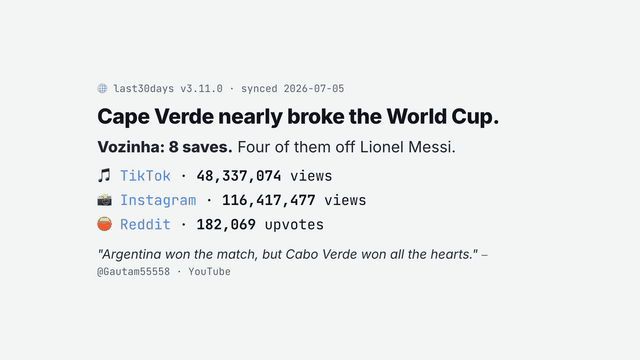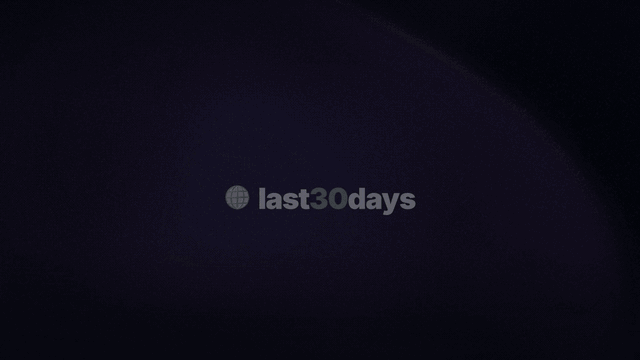
mvanhorn/last30days-skill abandons centralized scraping architectures. It deploys the AI agent directly to the user's local terminal, leveraging existing browser sessions and local API keys to concurrently dispatch tasks across a dozen heterogeneous data channels upon a single command. Instead of fetching structured data via monolithic APIs, the agent autonomously parses unstructured community dynamics, applying signal-weighting filters based on real user upvotes, engagement metrics, and financial stakes.
💡 Core Architecture Insight: By decentralizing scraping decisions to local AI agents across multi-source platforms, this project bypasses costly data procurement pipelines and centralized indexing, establishing a decentralized reconnaissance framework anchored on the user's personal context.
2. Core Architecture & Underlying Data Flow Analysis
The runtime lifecycle is defined by the specification in skills/last30days/SKILL.md. When a query is issued in the terminal, the client gateway passes the payload to the dynamic execution engine. The engine analyzes the target topic's characteristics and dispatches parallel fetching tasks to sub-modules including Reddit, Hacker News, GitHub, Polymarket, and arXiv. For platforms lacking public APIs, the system directly extracts rendered DOM nodes from local browser instances or leverages community-contributed CLI toolchains.
[ Client CLI / Claude Code ] ---> [ Gateway Parser ] ---> [ Task Dispatcher ]
                                                              │
        ┌─────────────────────────┬───────────────────────────┴───────────────────────────┐
        ▼                         ▼                           ▼                           ▼
[ Reddit Scraper ]     [ X / Twitter Worker ]     [ Polymarket Odds Engine ]     [ GitHub PR Analyzer ]
        │                         │                           │                           │
        └─────────────────────────┴───────────────────────────┴───────────────────────────┘
                                                              │
                                                              ▼
                                                   [ AI Agent Judge Synthesizer ]
                                                              │
                                                              ▼
                                                   [ Local Terminal Brief ]
The core of the data flow lies in scoring weight calculations. The system does not treat all fetched results equally. A Reddit post with 1,500 upvotes or Polymarket prediction odds backed by real money automatically triggers a weight boost by the engine. Conversely, traditional articles lacking user interaction are downweighted. Cleaned data and extracted key sentences from all channels converge into the underlying agent judge, where the large language model performs cross-validation and deduplication, eventually outputting a concise intelligence brief.
3. Technology Selection & Performance Comparison
| Evaluation Dimension | This Solution (last30days-skill) | Traditional Paradigm | Typical Competitor Solution | Production Yield |
|---|---|---|---|---|
| Data Source Coverage | 20+ heterogeneous platforms including Reddit, X, YouTube, Polymarket, GitHub | Single search engine or isolated social API | Perplexity Pro / ChatGPT Web UI | Captures frontline user feedback unindexed by traditional web |
| Auth & Cost | Zero-config start, supports BYO browser session and local CLI | Expensive enterprise API procurement and token bills | Commercial SaaS subscription with rate-limited quotas | Eliminates data acquisition overhead; full user control over session limits |
| Real-time Filtering | Dynamic weighting based on real user votes, likes, and financial stakes | Relies on static web crawling cycles and manual editorial review | Static training data slices inherent to LLM checkpoints | Blocks outdated information and PR noise, targeting the last 30 days |
| Deployment Topology | Plugin-based local agent embedded in Claude Code or generic Skill hosts | Centralized cloud microservice clusters with high ops overhead | Closed web dashboard without local pipeline customization | Zero operational burden; runs directly inside existing developer workflows |
The elegance of this technical selection lies in abandoning the pursuit of a unified data warehouse. By transforming the client into a multi-protocol router via the agent, each data source is loaded on demand, consuming zero remote or local compute resources when inactive.
4. Hands-on Geek Guide: Building a Minimal Loop from Scratch
Install the Skill in a production or local development environment. For the recommended Claude Code environment, load and run via the plugin marketplace:
# Add the last30days plugin directly to the Claude Code marketplace
/plugin marketplace add mvanhorn/last30days-skill

# Install the skill in the current working environment
/plugin install last30days

# Alternatively, perform global installation via universal Agent Skills host
npx skills add mvanhorn/last30days-skill -g
Once installed, execute the query command targeting a specific individual or technology stack in the terminal:
# Reference Python core invocation script simulating internal execution logic
import subprocess
import sys

def run_last30days_query(target_topic: str):
    # Assemble CLI execution parameters with zero-config mode and default output channel
    command = ["npx", "skills", "run", "last30days", target_topic]

    # Spawn subprocess and capture standard output streams in real time
    process = subprocess.Popen(
        command,
        stdout=subprocess.PIPE,
        stderr=subprocess.PIPE,
        text=True,
        encoding="utf-8"
    );

    # Stream lines generated by the agent judge synthesis
    for line in process.stdout:
        sys.stdout.write(f"[ENGINE_LOG] {line}")

    process.wait()
    if process.returncode != 0:
        raise RuntimeError(f"Agent execution failed with code {process.returncode}")

if __name__ == "__main__":
    # Execute multi-source penetration search on a specific open-source maintainer's 30-day activity
    run_last30days_query("Peter Steinberger")
Upon execution, the terminal outputs a comprehensive briefing covering the target entity's GitHub commit velocity, Reddit community dispute traction, X platform statements, and PR merge rates.
5. Production Gotchas & Mitigation Strategies
⚠️ Gotcha Warning [API Rate Limits & Browser Session Expiry]: High-frequency scraping of X or Reddit channels using unauthenticated local browser sessions easily triggers platform rate limits and security challenges. Ensure local default browsers remain logged in before execution, or configure dedicated proxy credentials via environment variables.
⚠️ Gotcha Warning [Token Consumption Runaway]: YouTube video transcripts and lengthy Reddit discussion threads contain massive amounts of unstructured raw text. Feeding all raw tokens blindly into the LLM judge creates prohibitive API costs per query. Configure strict character truncation limits per data source in configuration files, prioritizing the agent's built-in vector summary filter layer.