
1. The Core Bottleneck: What Engineering Dead Ends Does It Break?
LLM-driven engineering agents quickly saturate context windows when handling massive codebases and verbose logs. Developers repeatedly encounter skyrocketing API costs, frequent KV-cache invalidation, and tool-calling failures caused by attention drift over long texts. Cloud-based third-party compression solutions often introduce severe code leakage and compliance risks, while raw log streaming cripples network throughput.
Headroom positions the compression layer directly on the local host. All incoming data destined for the LLM—including tool outputs, file contents, RAG chunks, and conversation history—is cleaned, routed, and compressed locally. The model receives a pruned instruction set while retaining the ability to fetch original content on demand through local cache references, resolving the eternal tension between long-text throughput and inference accuracy.
💡 Core Architecture Insight: By combining local interception with content-aware pruning, Headroom protects data privacy boundaries while cutting off the supply of invalid tokens that degrade model attention.
2. Core Architecture and Data Flow Analysis
Headroom implements a multiplexed pipeline architecture. When a client or coding agent emits a prompt, the request first hits CacheAligner to evaluate volatile content that might bust the KV-cache prefix. It then flows into ContentRouter for automatic data type detection. The system dispatches payloads to SmartCrusher for JSON structures, CodeCompressor for Abstract Syntax Trees (AST), or the Hugging Face-hosted Kompress-v2-base model for prose.
 Your agent / app
   (Claude Code, Cursor, Codex, LangChain, Agno, Strands, your own code…)
        │   prompts · tool outputs · logs · RAG results · files
        ▼
    ┌────────────────────────────────────────────────────┐
    │  Headroom   (runs locally — your data stays here)  │
    │  ────────────────────────────────────────────────  │
    │  CacheAligner  →  ContentRouter  →  CCR            │
    │                    ├─ SmartCrusher   (JSON)        │
    │                    ├─ CodeCompressor (AST)         │
    │                    └─ Kompress-v2-base (text, HF)  │
    │                                                    │
    │  Cross-agent memory  ·  headroom learn  ·  MCP     │
    └────────────────────────────────────────────────────┘
        │   compressed prompt  +  retrieval tool
        ▼
 LLM provider  (Anthropic · OpenAI · Bedrock · …)
Compressed data streams integrate with CCR (Cache-Compressed Retrieval) local storage before reaching LLM providers. If an agent requires the original uncompressed text during execution, it invokes the locally registered headroom_retrieve tool. This decoupled reference-recovery pattern maintains lightweight transmission while keeping full-text rollback possible.
3. Technology Selection and Hardcore Performance Benchmarks
| Dimension | headroom | Traditional Paradigm | SaaS Alternative | Production Benefit |
|---|---|---|---|---|
| Data Privacy | Local execution, zero plaintext upload | Frequent cloud uploads | Managed third-party SaaS | Eliminates code asset compliance risk |
| Compression Strategy | Dedicated JSON/AST/Prose algorithms | Global truncation or crude drops | Native long-context models | Zero loss of vital error bytes |
| Agent Integration | One-click wrapping for CLI/MCP tools | Heavy SDK refactoring | IDE or framework specific | Zero code intrusion, fast rollout |
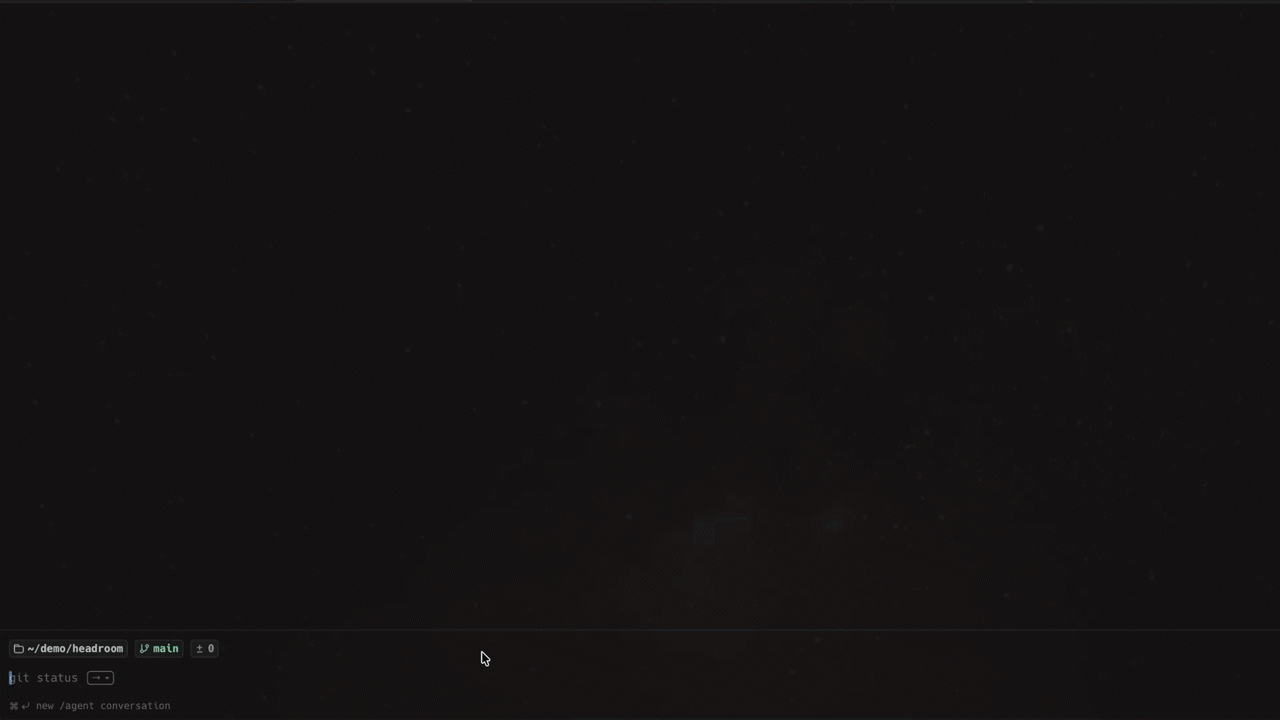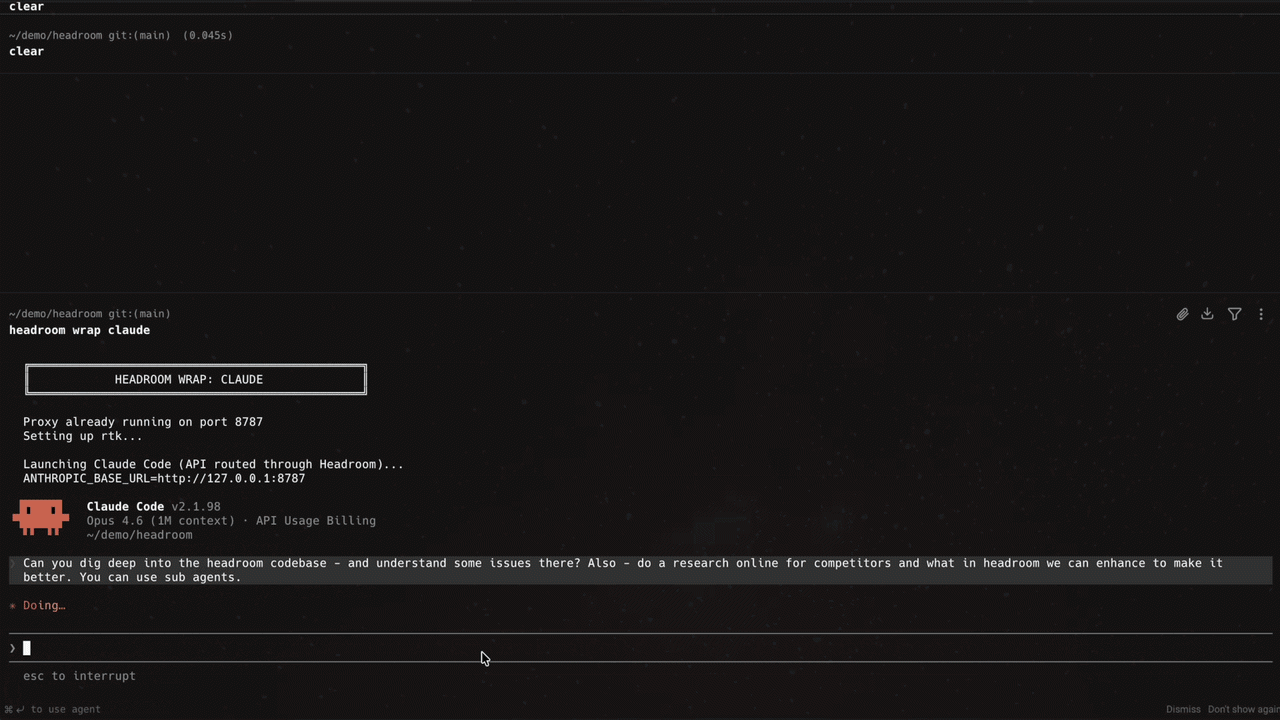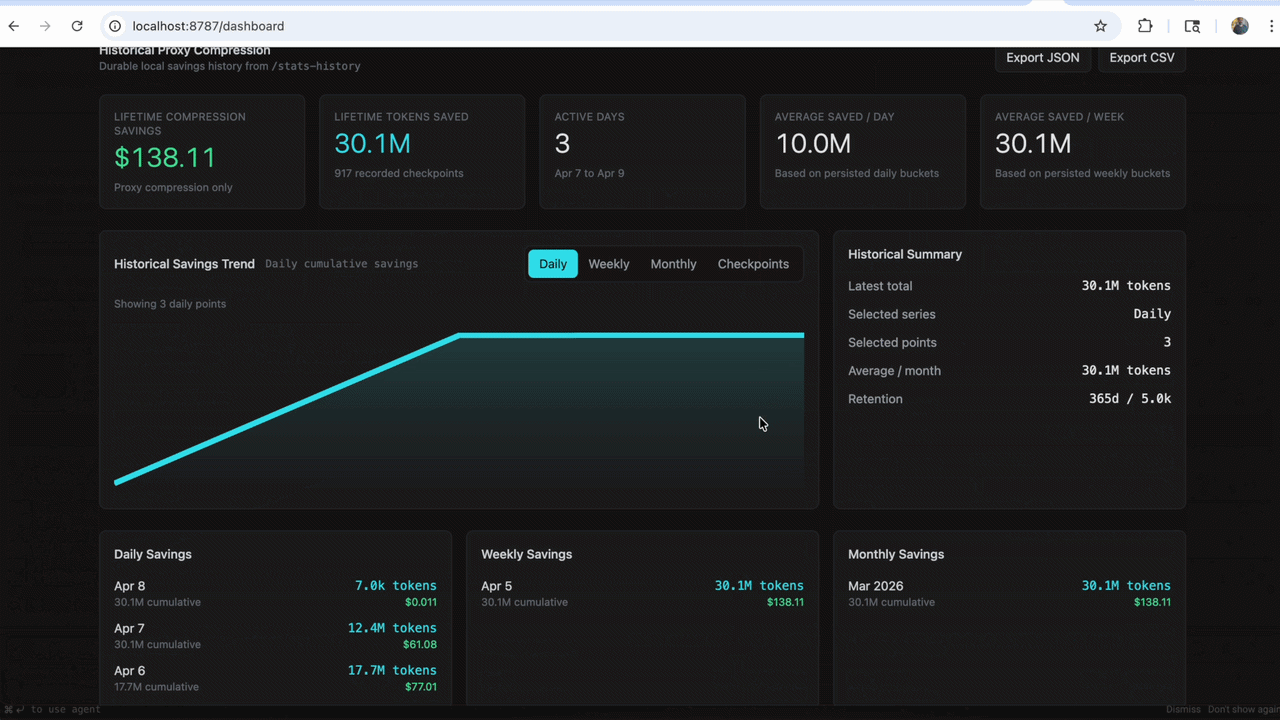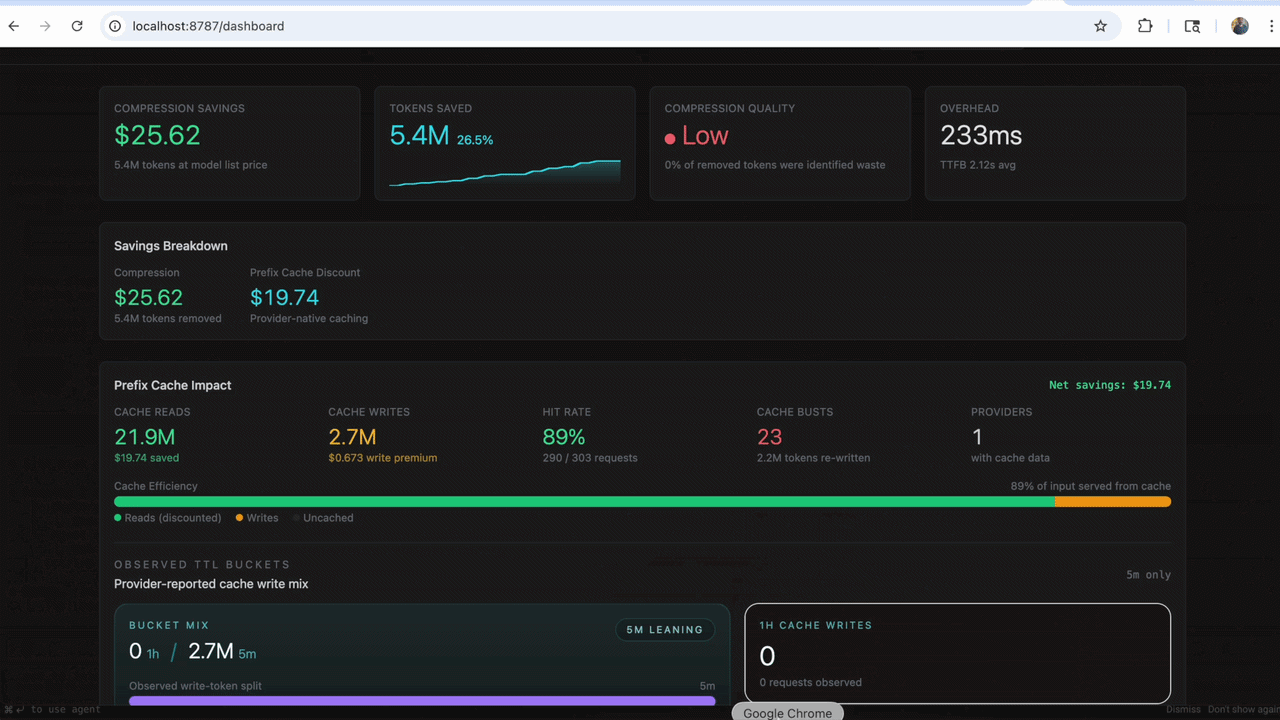
| Cost Savings | Up to 57% token reduction measured | High recurring API bills | Open-source chunking RAG | Direct reduction of compute expenditure |
Commercial LLMs impose steep fees and latency penalties for ultra-long contexts. Headroom rejects the illusion of infinite context windows, intercepting invalid text at the entry point using engineered compression and routing. This precise pruning minimizes unit request costs while preserving task completion rates.
4. Hands-on Geek Practice: Building a Minimal Closed Loop
In a Unix-like environment, install the package including the full CLI and dependencies using the uv tool:
# 1. Install headroom with all extensions in an isolated uv environment
uv tool install --python 3.13 "headroom-ai[all]"

# 2. Deploy the local proxy server listening on port 8787
headroom proxy --port 8787

# 3. Run health checks to confirm proxy and content routing function correctly
headroom doctor
Import the compress function inline in Python to intercept and compress LLM conversation histories:
from headroom import compress
from openai import OpenAI

# Construct the verbose raw message queue for analysis
messages = [
    {"role": "system", "content": "You are an SRE debugging assistant."},
    {"role": "user", "content": "Analyze these massive log results and find the root cause."}
]

# Invoke the local Headroom engine for compression, tuned for gpt-4o characteristics
result = compress(messages, model="gpt-4o")

client = OpenAI()
# Forward the compressed messages list to the OpenAI API endpoint
response = client.chat.completions.create(
    model="gpt-4o",
    messages=result.messages
)

# Print token savings metrics
print(f"Saved {result.tokens_saved} tokens ({result.compression_ratio:.0%})")
Executing headroom wrap claude takes over Claude Code agent sessions, automatically starting a local proxy in the background and attaching the Serena semantic code navigation module for cross-tool memory and compression coordination.
5. Production Gotchas and Avoidance Strategies
In multi-agent concurrent invocation or long-running automated script scenarios, the local cache directory can grow faster than anticipated. Unmanaged accumulation will eventually exhaust disk space.
⚠️ Gotcha Warning [Local Cache Bloat]: CCR local caching persists large amounts of raw text prior to compression. It is recommended to schedule periodic cache pruning commands in production servers or CI pipelines, or specify dedicated TTL retention policies via environment variables.
Certain proprietary or fine-tuned models are sensitive to non-standard prompt structures. Enabling aggressive AST compression via ContentRouter may occasionally shift the parse semantics of custom system instructions.
⚠️ Gotcha Warning [Custom Instruction Distortion]: If your business logic incorporates heavily customized DSLs or non-standard JSON protocols, avoid enabling aggressive compression blindly. Validate routing rules via
headroom doctorfirst, and explicitly exclude sensitive message segments in agent configurations when necessary.