
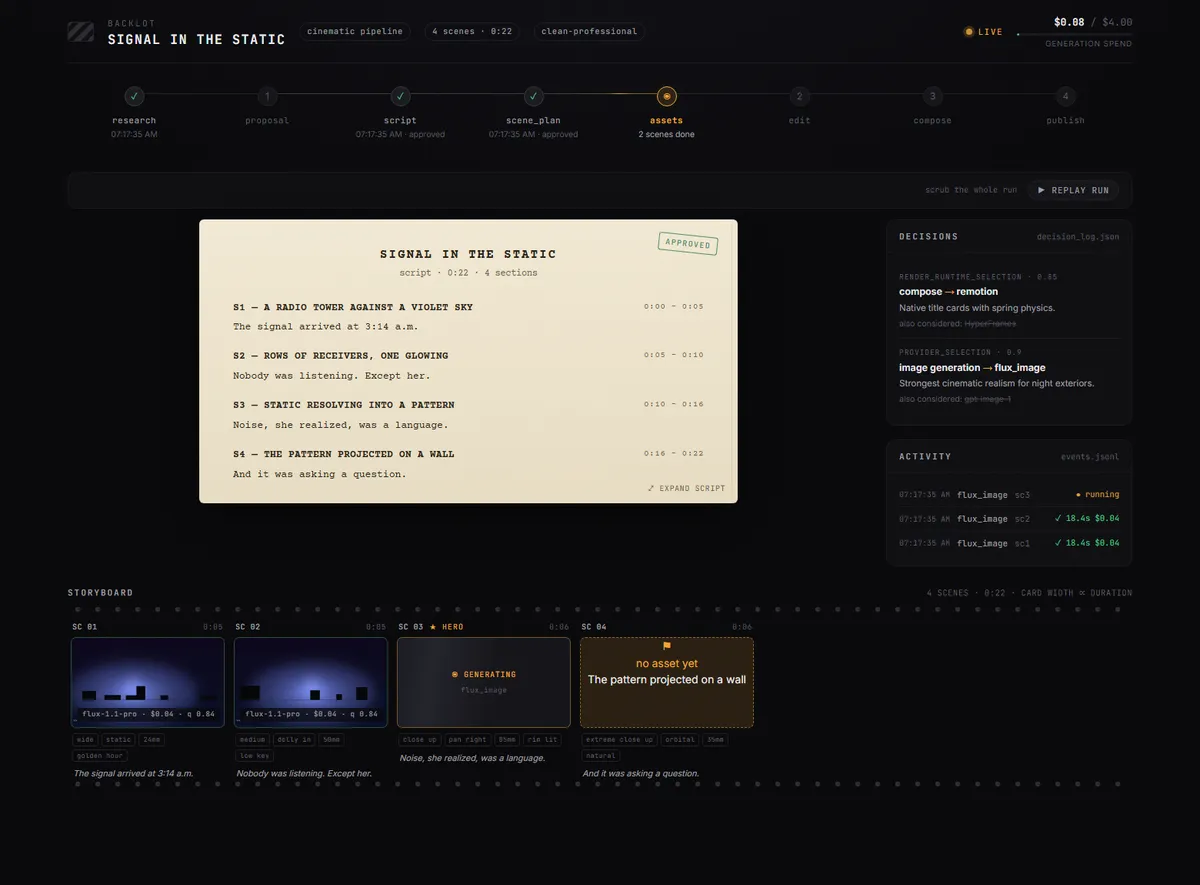
1. The Core Bottleneck: What Architectural Defect Does It Pierce?
The video generation ecosystem suffers from severe asset silos and engineering fragmentation. Developers typically invoke standalone image models to generate static frames, manually inject prompts to drive video models, and finally stitch timelines, voiceovers, and subtitles inside traditional non-linear editing software. This pipeline relies on manual glue code and mechanical labor, exhibits high error rates, rejects CI/CD integration, and completely lacks iterative natural language driving.
OpenMontage breaks this paradigm by tightly binding Large Language Model agents with programmatic video composition engines. The system takes full control of the entire lifecycle, spanning intent parsing, web asset scraping, multi-modal motion editing, and programmatic rendering. Developers no longer export intermediate files manually; prompts map directly to executable timeline rendering trees.
💡 Architectural Core Insight: Redefining video editing as structured code and agent state machine scheduling eliminates the manual friction costs inherent in traditional multimedia production.
2. Core Architecture and Data Flow Analysis
The runtime of OpenMontage decouples intent generation, asset discovery, and video composition through a layered agent architecture. The system ingests natural language prompts or reference video URLs, extracting transcripts, pacing, and keyframe features via multi-modal parsers. State machines then decompose tasks into scriptwriting, asset retrieval, dynamic generation, and Remotion/FFmpeg rendering subtasks.
[ User Prompt / Reference Video ] ---> [ Gateway & Multi-modal Parser ] ---> [ Context & State Memory ]
                                                                                 │
                                                                                 ▼
[ FFmpeg / Remotion Render Engine ] <--- [ Dynamic Task Execution Engine ] <--- [ Tool Router (Fal.ai / Blender / Stock API) ]
At the execution layer, the architecture discards black-box monolithic calls in favor of contract-driven asset generation pipelines. Each scene operates as an independent entity flowing through the context, with providers like fal.ai, Google Chirp, or local Blender renderers injecting parameters through unified interface specs. This design preserves visual continuity across multi-model generations, utilizing first/last frame pinning to eliminate identity drift.
3. Technology Selection and Hardcore Benchmarking
| Evaluation Dimension | OpenMontage Pipeline | Traditional NLE (Premiere/CapCut) | Legacy AI Web Tools (Runway) | Production ROI |
|---|---|---|---|---|
| Automation Level | Full agent pipeline orchestration | Manual drag-and-drop | Semi-automated web UI clicks | Eliminates labor, enables 24/7 batching |
| Asset Management | Dynamic open-source & API retrieval | Local folder manual sorting | Closed platform stock library | Controlled costs and copyright compliance |
| Rendering Mechanism | Code-driven Remotion / FFmpeg | Heavy desktop NLE export | Cloud-queued web rendering | Supports headless cluster scaling |
| Programmability | Full source-level control & prompting | Closed script plugins | Extremely limited APIs | Deep integration with DevOps systems |
This technology stack shifts video production from traditional manual labor into a standard software engineering problem. Sacrificing visual drag-and-drop interfaces yields infinite scalability and throughput, fitting engineering teams requiring high-frequency batch video generation.
4. Minimal Viable Setup: Zero-to-Production Guide
Deploying OpenMontage locally and executing the first automated video rendering task requires Python and Node.js environments.
# Clone the official repository
git clone https://github.com/calesthio/OpenMontage.git
cd OpenMontage

# Install Python core dependencies
pip install -e .

# Install Remotion rendering environment dependencies
npm install
Configure environment variables and execute the minimal pipeline script to initialize the agent and render a 60-second animated short:
import os
from openmontage import StudioAgent, ProductionConfig

# Load API keys from environment variables (e.g., fal.ai, OpenAI)
config = ProductionConfig.from_env(
    # Set default video generation provider to Kling model on fal.ai
    video_provider="fal-ai/kling-v3",
    # Set text-to-speech engine
    tts_provider="google-chirp3-hd",
    # Set target rendering framework
    render_engine="remotion"
)

# Instantiate the studio production agent
studio = StudioAgent(config=config)

# Submit natural language production instruction to drive end-to-end execution
production_job = studio.create_from_prompt(
    prompt="A 60-second Pixar-style animated short about a lonely banana finding friendship with a kiwi.",
    output_resolution="1080p",
    fps=30
)

# Execute rendering pipeline and print final output path
output_path = production_job.execute()
print(f"Production finished successfully. Output saved to: {output_path}")
Executing python run_production.py streams script parsing logs, asset download progress, and API cost statistics to the console, generating the finalized MP4 file in the output/ directory.
5. Production Gotchas and Mitigation Strategies
Integrating this system into production environments or high-concurrency task queues requires specialized hardening against API rate limits and large file I/O.
⚠️ Gotcha Warning [API Rate and Cost Explosions]: Multi-modal agents generate dense LLM and video synthesis requests during iterative script refinement. Enforce hard token consumption limits and per-task budget thresholds in configuration files to prevent runaway API billing caused by recursive correction loops.
⚠️ Gotcha Warning [Large Asset Cache Leaks]: Video rendering pulls substantial raw footage and 3D assets. Ensure execution environments implement automated temporary storage garbage collection to prevent disk exhaustion and FFmpeg crashes during continuous batch runs.